At 2:14 a.m., a payment platform sent a webhook. The receiving server was mid-deploy, so the connection timed out and the platform did what it is designed to do: it queued the event and tried again four minutes later. By then the first request had actually been processed — the ACK had just never made it back. The retry created a second payment for the same invoice. Finance discovered it two days later, when the supplier asked why they had been paid twice.
Nothing in that sequence was a bug in the payment platform. It was a design assumption on the receiving side: that one event means one write. Payment APIs are built on at-least-once delivery, which means duplicates are not an edge case to handle later — they are the normal operating condition. The teams that get this right treat webhook handling as a small distributed-systems project, not as a callback function.
This guide is about that project: what a payment webhook really promises, how idempotency keys work in practice, how to retry without amplifying an outage, and how to keep an event log that can answer "did we already pay this?" six months later. If you are still choosing a provider, the evaluation criteria live in the B2B payments API integration guide; this piece assumes you have one and need it to behave.
A duplicate payout is rarely a payments problem
When a duplicate payment is investigated, the conversation usually starts with the payment provider and ends with the ERP. The provider can show the event was sent three times, each time with the same event ID. The ERP can show three supplier payments were created. Both are correct. The gap is in the layer between them: the code that received the event, decided it was new, and wrote to the ledger.
That layer has three jobs, and most incidents trace back to one of them being skipped:
Identify. Decide whether this event has already been applied. This is the idempotency problem, and it must be solved before any money-related write, not after.
Order. Accept that payment.settled can arrive before payment.created, especially when retries and multiple queues are involved. The handler cannot assume a sequence just because the provider generated one.
Prove. Keep enough of the raw event to reconstruct what happened. When a controller asks why a payment posted on the 14th and reversed on the 16th, "the logs rolled over" is not an answer.
What a payment webhook actually guarantees
Almost every payment API documents three things about webhooks: the event types, the signature header, and the retry schedule. It is worth reading all three carefully, because the guarantee is narrower than most integrators assume.
Delivery is at-least-once, never exactly-once. The provider will keep retrying until it receives a successful response or gives up. A response that is slow, a load balancer that drops the connection, or a process that crashes after committing but before replying all produce the same outcome: another delivery of the same event.
The signature proves origin, not freshness. An HMAC signature over the raw body with a shared secret tells you the event came from the provider. It does not tell you the event is new. Replay protection needs a timestamp tolerance and a record of event IDs you have already seen — the signature alone will happily validate the same payload for the tenth time.
Retries are not ordered. If event A fails and event B succeeds, the retry of A arrives after B. This is normal, and it is the reason handlers should be able to move a record forward from any state rather than expecting a clean sequence.
One practical rule follows from all three: acknowledge fast, process carefully. Respond with a 2xx as soon as the event is durably queued, then do the work in a worker that can be retried on your side too. Holding the HTTP connection open while you call the ERP is how timeouts and duplicate deliveries get created in the first place.
Idempotency keys, without the hand-waving
An idempotency key is a value that lets the receiver recognise a repeat. In payments there are two places it matters, and they are often confused.
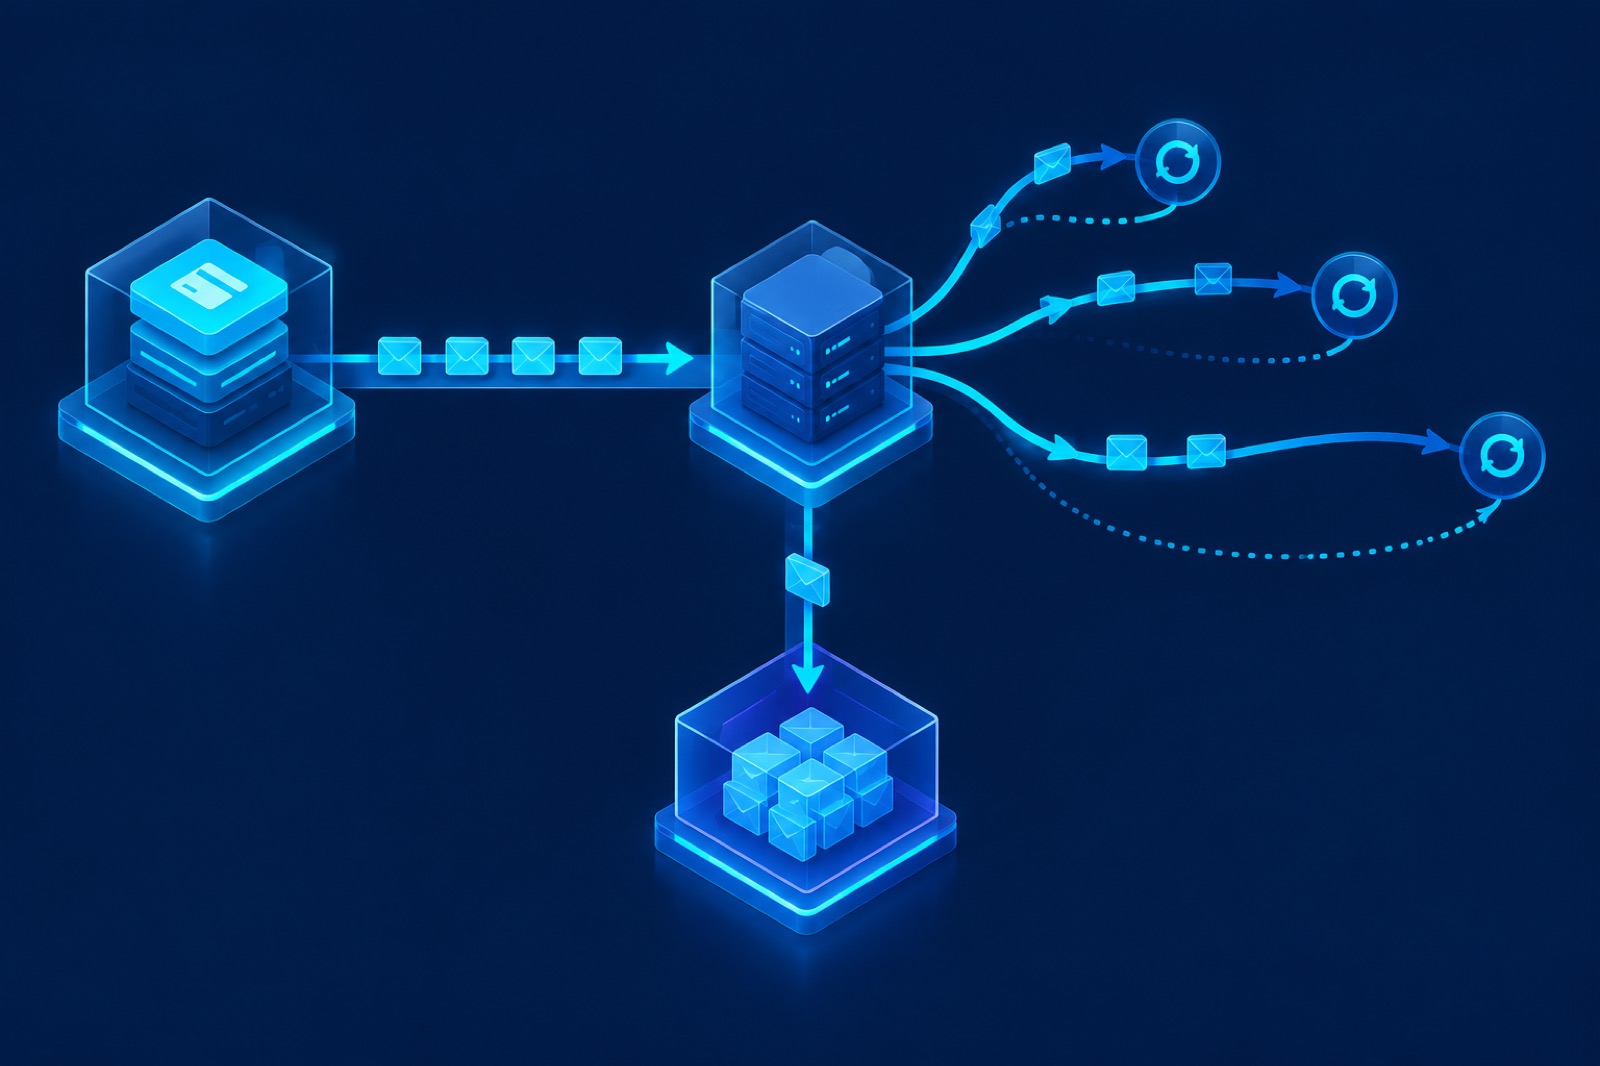
Outbound keys. When your system calls the payment API to create a payout, you send an idempotency key in the request header. If the call times out and you retry with the same key, the provider returns the original result instead of creating a second payout. This protects you against your own retries. Generate the key from the business object — the invoice ID plus the payment attempt number works well — and store it before the first call, not after.
Inbound keys. When the provider calls you, the event ID is the key. Store it in a table with a unique constraint and attempt the insert first. If the insert fails because the ID already exists, you have seen this event: return 200 and do nothing else. If it succeeds, process the event. The unique constraint, not application logic, is what makes this safe under concurrent deliveries.
The subtle part is where the key is checked relative to the write. A pattern that looks correct and is not:
if not event_exists(id):
    create_payment(event)      # crash here → payment exists, record does not
    save_event(id)
If the process dies between the two steps, the next delivery sees no event record and pays again. The fix is to make the deduplication record and the business effect land in one transaction, or to make the business write itself idempotent through a natural key — for example, a unique constraint on (invoice_id, payment_attempt). Either approach works; the one that does not is a check-then-write across two systems.
There is a second-order case worth planning for: the same business event arriving under two different event IDs. Some providers emit both a payment.completed and a transaction.settled for one movement of funds. Deduplicating on event ID will not catch that. Deduplicating on a business key — provider reference, amount, currency, and value date — will.
Retries that don't make things worse
Retry logic is easy to write and hard to write well. The failure mode is a handler that retries immediately, several times, while the downstream ERP is already struggling. That turns a brief outage into a self-inflicted flood.
Three controls do most of the work:
Exponential backoff with jitter. Wait, then wait longer, and randomise the interval so that thousands of events do not retry in lockstep. A schedule of roughly 1 minute, 5 minutes, 30 minutes, 2 hours, 6 hours covers a typical provider outage without holding events hostage for days.
A dead-letter queue with an owner. After the last retry, the event should land somewhere a human can see it, with the payload, the error, and the attempt count intact. A dead-letter queue nobody monitors is just a quieter way to lose payments.
A circuit breaker on the downstream. If the ERP is returning errors for every call, stop calling it for a few minutes and let the queue absorb the load. The events are already durable; there is no prize for hammering a system that is down.
Two more rules are worth writing into the runbook. Retries must be idempotent — a retry that creates a second record is worse than no retry at all. And retries must have a ceiling: an event that has failed for 24 hours needs an alert and a decision, not another silent attempt.
Ordering: assume nothing, reconcile anyway
The clean mental model is that webhooks are notifications, not the source of truth. The source of truth is the payment record you can query. A handler that receives payment.settled for a payment it has never seen should fetch the payment by ID and create it in the correct state, rather than dropping the event or writing a half-record.
This is also where the event log earns its keep. Keep every raw payload with its signature, receipt time, and processing outcome. It costs very little, and it turns a class of incidents from forensic archaeology into a query. When an auditor asks which events touched a given payout, the answer should be a list, not a reconstruction from application logs.
Ordering problems that survive this approach usually show up as reconciliation breaks rather than payment errors: a settlement posted against an invoice that was cancelled, or an FX difference applied twice. Those are easier to catch when the payment record carries an explicit state and the ledger write is driven by transitions rather than by individual events. The reconciliation automation guide covers the matching side; the point here is that a clean state machine prevents most of the breaks before matching even starts.
The state machine your ledger expects
Write the states down before writing the handler. A payment that can be in six states is far easier to reason about than one with a boolean "paid" flag, and it gives the ledger something stable to post against.
| State | Entered when | What the ledger does |
|---|---|---|
| Initiated | Payout accepted by the provider | Nothing; no accrual yet |
| Submitted | Provider confirms it is on the rail | Optional memo entry only |
| Settled | Funds confirmed at the beneficiary bank | Post payment and clear the payable |
| Returned | Funds come back after settlement | Reverse the entry, reopen the invoice |
| Failed | Provider rejects before settlement | Nothing; flag for retry or repair |
| Closed | Reconciled to the bank statement | Lock the record and the evidence |
Two details make the difference between a state machine that helps and one that creates arguments. Transitions should be forward-only with explicit allowed edges — a settled payment can move to returned, but never back to submitted. And every transition should carry the event ID that caused it, so the audit trail answers "why is this payment in this state" without a meeting.
For teams posting into an ERP, the same discipline applies on the other side: the ledger entry should be keyed to the payment ID, not to the event that happened to arrive. If the integration is connector-based rather than custom, check how it behaves on a replayed event — that question belongs in your native ERP integration evaluation.
What to test before the first live payout
Most teams test the happy path and ship. These are the tests worth writing before real money moves:
- Duplicate delivery. Send the same event twice, concurrently, and confirm exactly one payment exists.
- Out-of-order delivery. Send settlement before creation and confirm the handler fetches and lands in the right state.
- Signature replay. Re-send a valid payload outside the timestamp tolerance and confirm it is rejected.
- Slow downstream. Add two seconds of latency to the ERP call and confirm the webhook still acknowledges within the provider's timeout.
- Crash after write. Kill the worker between the payment write and the event record, then redeliver. This is the test that exposes check-then-write patterns.
- Dead-letter recovery. Force an event into the dead-letter queue, then replay it and confirm the replay is idempotent.
Run these against the provider's sandbox, then again in production with a single low-value supplier before the first batch. The cost is an afternoon; the alternative is the 2:14 a.m. version.
Questions to put to a payment provider
If you are choosing rather than maintaining, the answers to these separate a mature API from a demo:
"What is the retry schedule, and what happens after the last attempt?" You want a published schedule, a dead-letter behaviour you can query, and a replay endpoint. A provider that says "we retry for 24 hours" and has no replay API leaves you reconciling by hand.
"Do you support idempotency keys on every write, and how long do you retain them?" Retention matters: a key that expires in an hour does not protect a payment that retries overnight.
"Can I query the payment record independently of the webhook?" If the only way to learn a payment's state is to wait for an event, you cannot recover from a missed delivery.
"How do you signal a reversal or a return?" Reversals are where event models get sloppy. A provider that reuses payment.updated for everything forces you to parse free text; distinct event types and a status field are better.
Good answers here also shorten implementation. If the API exposes a payment state you can poll and a replay endpoint for events, the receiving service can stay small — which is exactly what you want, because every line of custom payment logic is a line that has to be audited. Once payments do post cleanly, the next bottleneck is usually the close itself; payment to ledger picks up from there.
The short version
Payment webhooks are a notification system with at-least-once semantics, not a reliable queue with exactly-once delivery. Design for duplicates, because duplicates are coming. Use the event ID as a deduplication key backed by a database constraint, keep the business write and the deduplication record in the same transaction, retry with backoff and a monitored dead-letter queue, and treat the payment record — not the event stream — as the source of truth.
None of that is exotic. It is the standard shape of any system that moves money. The teams that skip it are not unlucky when the double payment happens; they are on schedule.